
How We KnowAnswer
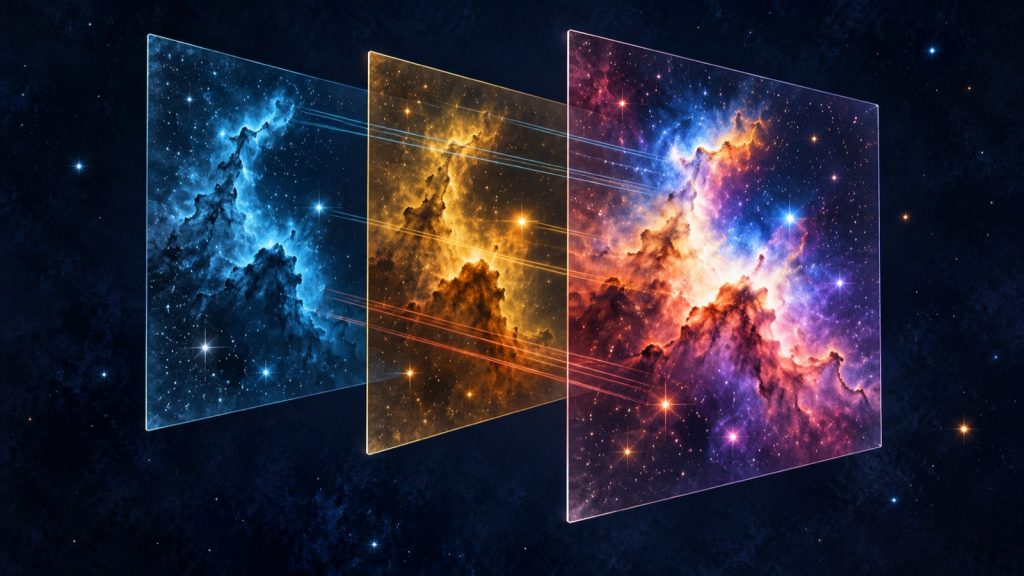
Are the colors in space photos real?
A space image can be faithful to measured light without matching human eyesight. Here is how to read the translation.
THE QUESTION LIBRARY HOW WE KNOW
How scientists distinguish real signals from lucky fits: look-elsewhere effects, independent predictions, black-hole searches and data-window artefacts.
A pattern becomes convincing when it survives checks that could have exposed a mistake: a fair comparison with noise, allowance for all the searches performed, independent tests and scrutiny of the measuring equipment and analysis. A formula that fits familiar numbers is a starting point. It becomes stronger evidence when it predicts something it was not adjusted to fit, with clear uncertainty and plausible alternatives considered.
WHAT WE DON’T KNOW YET
No single significance threshold eliminates every error. A particular new claim needs its actual search history, data-quality evidence and noise assumptions examined.
WHAT WOULD CHANGE THIS ANSWER
An independently repeated result that survives broader search corrections and alternative noise models would strengthen a candidate claim.
A striking pattern asks for an explanation. Before treating it as a discovery, scientists also ask how easily the same search could have found something striking in data with no such signal.
Free long answer 1 of 3 this month.
With enough adjustable freedom, a curve can be made to pass through a finite set of points, even if those points came from noise. A restricted set of formulas does not guarantee a good fit. The problem is hidden freedom: changing constants, choosing favourite numbers or discarding awkward cases until something works.
The “look-elsewhere” effect concerns opportunities to find a chance result. Gross and Vitells analysed it for particle searches: an excess at one chosen location is less surprising if a similar excess anywhere in a broad range would have counted as a discovery. A fair significance calculation accounts for that search.
Researchers can simulate signal-free data and repeat the whole search, recording its strongest result each time. Comparing only one favourite result with one fixed test would miss those extra opportunities.
A proposed relation must say what quantities it connects, what units and uncertainties apply, and where it should work or fail. Its adjustable choices must be visible. It should make a testable claim that differs from existing explanations, rather than just redescribe selected numbers.
For example, changing from metres to centimetres should not destroy a claimed physical relationship when the quantities and units are handled correctly. Finding an attractive numerical resemblance without explaining such choices gives us a question to investigate, rather than a new law.
A fit uses known results to choose a model. A clean prediction tests data that did not influence those choices. Those can be future observations or existing measurements deliberately kept aside.
This prevents the model from adjusting itself to the very evidence offered as its test. One independent, precise success can therefore be more informative than many flexible fits to the same information. It is not an automatic rule: prediction quality, uncertainty, alternatives and the independence of each test matter. Repeated independent successes can be stronger still.
In the GW150914 discovery analysis, researchers checked consistency between two separated LIGO detectors and used different search methods. They estimated accidental coincidences by shifting one detector's data in time, breaking the timing expected for a shared signal. They also investigated instrumental and environmental disturbances. These checks supported the detection; the result was not based simply on a visually pleasing waveform.
Fainter candidates need their own noise and instrument checks. The safeguards used for a well-established event cannot automatically establish every later claim about a black hole.
Yes. Cutting a stream of measurements into a sharply bounded segment can spread power between frequencies and introduce misleading relationships. The LIGO–Virgo analysis guide demonstrates this problem, called spectral leakage. Smoothly tapering the segment's edges reduces it.
Trying many start times, durations or filters and reporting only the most impressive result adds a separate selection problem. Noise comparisons must reflect those choices too. Processing is necessary, but its effects must be tested.
A statistical signal also depends on assumptions about noise. An unlikely result under one noise model does not directly give the probability that a proposed explanation is true. For the physical background, see gravity and spacetime; for personal interpretations, see why coincidences feel meaningful.
THREE THINGS TO REMEMBER
Are the colors in space photos real?
Space photos often show real measurements, but their colors may represent light our eyes cannot see.
God Plays Dice answers big questions in plain words, with sources and one of six honest labels.
See a mistake? Report a problem. Corrections are made openly.
CONTINUE THE THREAD
How We KnowAnswer
A space image can be faithful to measured light without matching human eyesight. Here is how to read the translation.
How We KnowAnswer
Why anecdotes feel convincing, what individual cases can show, and how to assess a confident judgment.
How We KnowAnswer
Random outcomes can form real streaks. Learn how independent events, chance models, and face pareidolia help explain luck and perceived patterns.
The Architect AI companion · All Access
Labels describe the evidence for a claim, not the people who hold it.
Match my phone uses your device’s light or dark setting.